Here is how to determine whether repeated disruptions to flights, banks, and email are outages or cyberattacks.
Nov 20, 2026
The main takeaway is blunt: when a service many people depend on stops working, the most likely culprit is not a hacker but an ordinary failure in human-operated, interdependent technology. That judgment matters because outage reports can spread fast. When 52,846 readers told Tom's Guide in a poll that they were hit by the Outlook outage, the 52,846-reader reports showed how disruptive one breakdown can be. They also showed how quickly speculation about hackers or a coordinated cyberattack can appear when an essential service stalls.
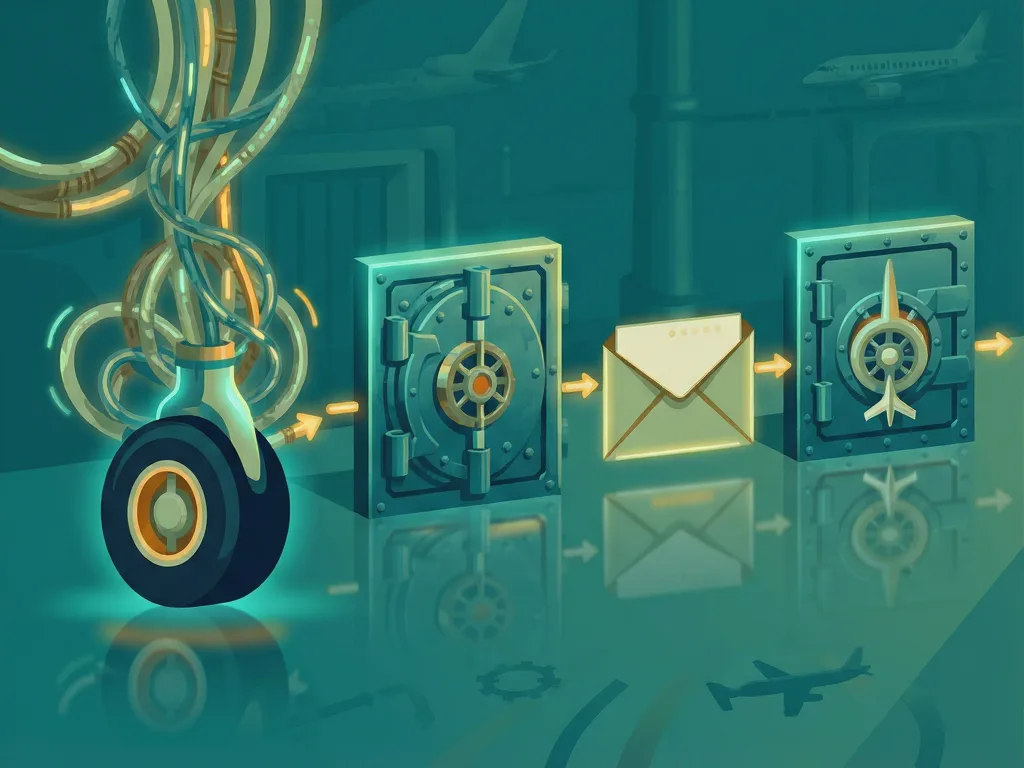
The more useful question is not only whether a failure happened, but what kind of failure it is. If a bank app freezes or a flight gets delayed by a system breakdown, readers need a practical way to separate accident from attack.
The 52,846-reader signal behind the rumor cycle
Large-scale outages feel dramatic, but the pattern behind them is often mundane. Digital services rely on millions of lines of code and overlapping networks, which means things break constantly. Most major outages trace to mundane technical failures and human error: a botched software update, a mistyped setting, a severed underground fiber cable, or a simple power failure. Unless concrete evidence of hacking emerges, an accidental technical error is almost always the safest bet.
Data supports that default assumption. According to the Uptime Institute, human error directly or indirectly contributes to between two-thirds and four-fifths of all data center downtime incidents. Roughly 85 percent of those human-error outages stem from staff failing to follow procedures or flaws in the procedures themselves. That statistic points to an important distinction: the problem is not only a person making a mistake, but also a process that lets the mistake spread.
Why one failure can make many services look broken
A second reason rumors spread is that modern services are interconnected. When one major service goes down, it often creates a domino effect that makes other apps look broken too. A payment failure at a single large bank can stall transfers at several others. A single cloud provider outage can knock dozens of unrelated websites offline at once.
That interdependence means the visible symptom may appear far from the root cause. A user may see an Outlook failure, a bank transfer stuck, or an airline dashboard warning and assume the company itself was attacked. In many cases, the company may be waiting on another partner to come back up. Major tech platforms, banks, and airlines maintain live dashboards that explain whether their systems are actually offline or just waiting on another partner to come back up.
Four ways to tell an outage from a cyberattack
The practical framework is to treat a major breakdown as an accident first, then test that assumption through independent verification, repair speed, and official confirmation. There are 4 ways to tell an outage from a cyberattack.
1. Assume it is an accident first
Start from the most common explanation. Because outages are common and hacking evidence is rare, the first explanation should be ordinary failure. The Outlook outage example, like any essential service stall, should not automatically be read as malicious hacking.
2. Verify the failure outside social media
Rather than trusting panicked posts on social media, check an independent outage tracker like Downdetector to see if other users are reporting problems nationwide. Search for the company's official status page and verified newsroom account. These channels are more useful than panicked posts on social media, because they can show whether the problem is broad or tied to another partner.
3. Watch how fast the problem gets fixed
The timeline of an outage is often one of the biggest clues to its cause. When an engineer pushes a bad update or a server overloads, companies can usually undo the change, reroute traffic, and restore service within a few minutes or hours. Widespread system crashes can occasionally take longer to untangle, but that still points to an operational problem, not necessarily an intrusion.
Deep-seated cyberattacks take much longer. Ransomware breaches require companies to lock down their networks, investigate the intrusion, kick intruders out, and rebuild damaged systems from scratch. That process regularly drags on for days or even weeks. If a service returns quickly, the evidence leans toward a recoverable technical fault. If it remains dark for days, a more complex incident may be involved, though that still does not prove a hack.
4. Do not jump to conclusions
In the first few hours of a major breakdown, nobody, not even the company experiencing the crash, always knows the exact root cause. This is where rumors fill the gap. When hackers are behind a major disruption, they often claim credit publicly to demand ransom or score political points. In other cases, federal cybersecurity officials eventually confirm a breach after investigating. Until an affected company or government agency shares verified findings, patience is the best defense against bad rumors.
What this means for readers
The biggest risk for readers is not only the outage itself, but the confusion during the uncertainty window. A stalled bank app or delayed flight can trigger fear and the spread of false explanations. The safer response is simple: look for independent outage data, check the company's official status page and verified newsroom account, and watch the repair timeline.
This approach also helps readers understand scale. If a single failure makes dozens of unrelated websites look broken, the problem may be a partner or infrastructure failure. If a payment failure stalls transfers at several banks, the issue may be a partner system. If a service comes back within minutes or hours, an accidental technical error is more plausible than a long, messy intrusion.
None of this eliminates risk. It only improves judgment. The Outlook outage reminder is not proof that every incident is accidental, and a fast recovery does not prove innocence. But it shows why the default assumption should be accident first: most widespread outages usually come down to ordinary human error or fragile infrastructure rather than malicious hacking.
Related guidance from Tom's Guide
Tom's Guide also pointed readers toward related privacy and resilience guides: How to remove your home address from the internet - 6 ways to protect your privacy; From Stolen Device Protection to iOS 27's new Impersonation Risk Detection, here are 5 iPhone security settings you need to turn on right now; and I audited my home for a 3-day blackout: 5 critical things I completely missed.
The publication asked readers to follow Tom's Guide on Google News and add it as a preferred source by clicking the Follow button. The article was shared through Facebook, X, Reddit and Email, with images credited to Shutterstock, Getty Images and Future.
Related Apps
 ted apk for android tv v7.5.33May 16, 2024 / 43mb
 Microsoft Edge v125.0.2535.51May 23, 2024 / 143.43M
 Replika: My AI Friend Apk v11.23.2Apr 24, 2024 / 946.1Mb
 TVB Stuttgart APK v0.5.0Jul 22, 2024 / 112.81Mb
 Never Saint Game Apk v1.0Jul 31, 2024 / 632.10Mb
 CaTgirl: AI Chat and Training Game Apk v1.0Jul 31, 2024 / 632.10Mb
Recommend Apps


